When the Cloud Gets Too Hot
At 7:20 PM ET on May 7, 2026, multiple chillers failed in an AWS data hall, according to Coinbase. By 7:48 PM, the exchange had reached a near-total trading halt.
The customer never sees the chiller. They see a trade that will not go through.
Four outages in 2026 show how quickly a cooling problem can become a software problem, and why recovery can take much longer than the original fault. An earlier result from Meta shows the quieter version: no outage, but less work getting done.
These were facility cooling and thermal incidents, not documented failures inside GPU cold plates. That distinction matters. Liquid cooling still needs a working route for heat to leave the building.
When a chiller failure stops trading
AWS Health recorded a thermal event in one US-EAST-1 data center. Virtual servers and their attached storage lost power as equipment shut down at temperature limits. Coinbase identifies failed chillers as the trigger.
The shutdowns left Coinbase with a second problem: getting its trading systems working again. At 9:29 PM ET, three of five matching-engine nodes were terminated. The cluster lost quorum, the minimum number of machines that must agree before it can proceed.
There was no automated cross-zone failover for that system. A separate defect in the managed Kafka messaging service complicated recovery. Severe disruption lasted roughly 8 hours; full recovery of all systems took another 12.
Think of a restaurant losing its kitchen. Moving diners to another room does not help if the food still comes from the same place. Software redundancy needs a matching physical design.
Cooling is back. Why is the service still down?
On May 29, 2026, a thunderstorm caused voltage dips and rises in Azure West US 2. Power did not disappear completely. The instability was enough to put some cooling equipment into protective lockout, preventing it from restarting automatically.
Operators had to restore cooling before bringing infrastructure back in stages. Cooling was restored at 05:55 UTC, about 91 minutes after customer impact began. By 12:00 UTC, about 95 percent of affected virtual machines had recovered. Storage checks took longer; telemetry backlogs were not cleared until 02:30 UTC the next day.
Restoring cooling was the beginning of recovery, not the end. Like reopening a railway after a signal fault, getting the equipment working does not instantly put every service back on schedule.
Three milliseconds, hours of recovery
On July 15, 2026, Google Cloud recorded a 3 millisecond utility voltage drop at a facility serving europe-west4-a. Breakers tripped, and backup-power problems disrupted equipment in the data hall.
A chiller controller went offline and could not tell the distribution pumps to restart. Redundant cooling was unavailable because of construction. With heat removal impaired, the data hall reached 44 C. That was the room temperature, not a GPU temperature.
Hosts, storage, and network equipment were shut down to protect hardware and data. Google reports an overall incident duration of 14 hours and 55 minutes, with different impact windows for individual services.
The useful question is not just whether a second chiller exists. It is whether the controls, pumps, power, and maintenance state allow that backup to work when needed.
When a whole fleet warms together
On August 13, 2026, back-to-back utility interruptions took all four chillers offline at Blacksmith's Phoenix facility. Its NVMe storage-drive temperatures rose across the fleet. An alert fired at 09:37 UTC as drives crossed 85 C, compared with a usual range in the 50s and 60s C.
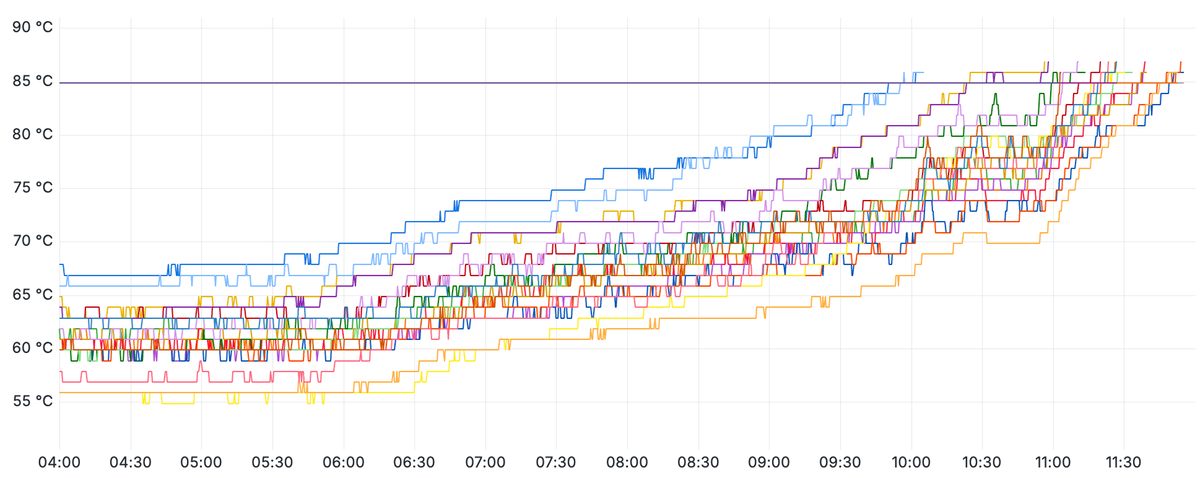
Storage failed first. Roughly 2,400 hosts were unavailable at peak. The remote-management network also failed, leaving engineers unable to power-cycle machines for much of the day.
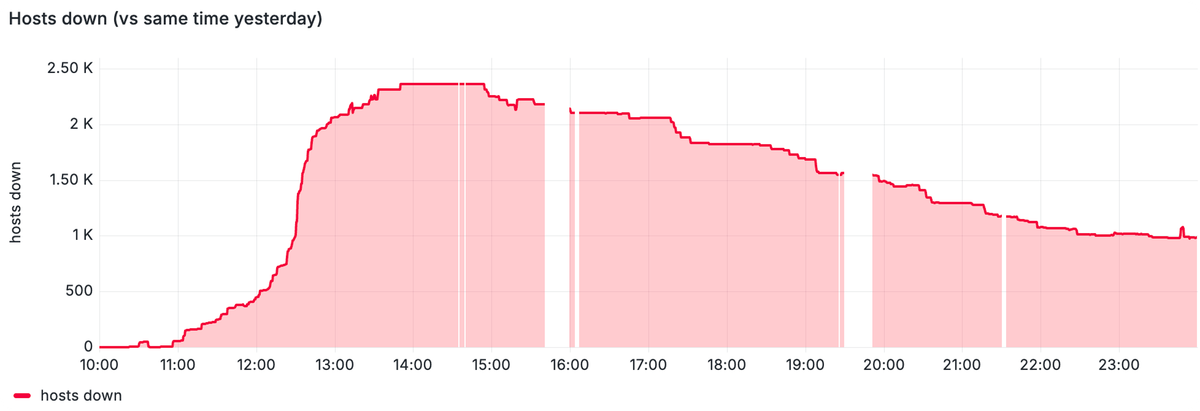
These are storage temperatures from this incident, not universal GPU or coolant alarm limits. The transferable lesson is to compare sensors across the fleet: shared movement can reveal a shared cooling problem.
No outage, but less work gets done
Meta's 2024 paper, The Llama 3 Herd of Models, describes a different cost of heat. During Llama 3 405B training, throughput varied by 1 to 2 percent with the time of day. Higher midday temperatures affected how GPUs adjusted their voltage and clock frequency.
That is a variation in training speed, not a measured loss of 1 to 2 percent of the fleet's full-day capacity. It shows that thermal conditions can affect useful compute without causing an outage.
Synchronized training is like a group waiting at each checkpoint: the next stage cannot start until the slowest participant arrives. Meta separately notes that a single slow GPU can hold back thousands of others. The paper does not attribute every such slowdown to heat, but it makes clear why operators care about performance, not just uptime.
Liquid cooling still needs somewhere to send the heat
A cold plate gives heat a short route out of a chip. It does not make that heat disappear.
In a common liquid-to-liquid design, rack coolant carries heat to a coolant distribution unit, or CDU. A heat exchanger inside the CDU transfers that heat to a separate facility-water loop. The two fluids stay apart. The facility must then reject the heat through its own cooling plant.
A heat exchanger is a bridge. If the far side cannot accept traffic, the near side eventually backs up.
For steady flow without boiling, the heat carried by coolant depends on three things: its mass flow rate, its specific heat capacity, and its temperature rise through the equipment. Specific heat capacity describes how much energy it takes to warm a given mass of fluid.
This is why the supply-to-return temperature difference, often called delta T, is not a health score. More heat at the same flow raises delta T. Less flow at the same heat load also raises it. You need load and flow alongside temperature to tell those situations apart.
Rack-side problems add another layer: restricted passages, trapped gas, leaks, pump faults, or a change in coolant chemistry. The outage reports above do not establish those causes. They show why every part of the heat-removal route matters, including the fluid moving through it.
What to watch together
One bottle collected on commissioning day cannot describe a loop for the rest of its life. A useful baseline records how a known-good system behaves across operating loads. Continuous fluid monitoring and operating telemetry let you compare today's loop with that history, including what changed after maintenance or a top-up.
The patterns below are starting points for investigation, not automatic diagnoses. A sensor fault or a workload change can imitate a cooling fault.
| Observed change | Possible explanation | Check next |
|---|---|---|
| Facility and rack supply temperatures rise together at similar load. | The facility supply or its control setpoint may have changed. This alone does not prove heat-exchanger fouling. | Facility cooling, flow, setpoints, and sensor accuracy. |
| Pump command rises while branch flow falls. | A restriction, trapped gas, valve position, or pump condition may have changed. | Pressure readings, valves, filters, pump state, and flow sensors. |
| GPU temperature rises at comparable load, local flow, and coolant supply temperature. | Resistance to heat transfer between the package and coolant may have increased. | Thermal interface, cold plate, local measurements, and workload transients. |
| Chemistry changes after a top-up or maintenance. | Fluid composition, contamination, or the measurement conditions may have changed. | Fluid specification, added fluid, temperature compensation, and confirmatory sampling. |
| GPU clocks or throughput change with temperature. | Thermal controls may be limiting performance. Other bottlenecks can look similar. | Hardware limit indicators, power caps, firmware, scheduling, and network delays. |
Use limits from the approved equipment and fluid specifications and the site operating plan. Allow for sensor accuracy and the conditions under which the baseline was recorded.
Five questions for the next cooling review
- What can fail together? Check whether supposedly independent racks or services share power, heat rejection, controls, network, or storage. Include temporary maintenance states.
- How much time would we have? Use an approved engineering analysis and controlled test plan to establish the margin before derating or shutdown. Do not discover it by overheating production hardware.
- Would monitoring still work? Check power and network dependencies for sensors, controllers, remote management, recorded data, and alerts.
- What must restart first? Rehearse the recovery sequence for cooling, controls, network, storage, compute, and customer workloads.
- What has changed since the loop was healthy? Review flow, pressure, temperature, fluid chemistry, maintenance, and useful compute together, not as unrelated dashboards.
Where Reliability Engine helps
Plant controls tell you about the building. Server sensors tell you about the hardware. The coolant needs attention too, from the first fill through everyday operation.
Reliability Engine brings fluid monitoring and predictive analysis to that gap. It helps teams interpret continuous cooling-loop telemetry against known-good operating conditions, so changes in the fluid and the loop can be investigated in context.
That complements facility controls, CDU safeguards, commissioning tests, and laboratory analysis. It does not replace them, prevent a grid disturbance, or guarantee that an outage will be avoided.
The aim is practical: when a temperature moves, know what else moved with it. A workload can keep running only while its heat has somewhere to go.
Planning or operating a liquid-cooled facility? Talk to Reliability Engine about continuous fluid monitoring.
Subscribe to updates
Get the latest engineering perspectives sent straight to your inbox.
References
- AWS Health: EC2 thermal event in US-EAST-1, May 7, 2026
- Coinbase: A postmortem of the May 7, 2026 outage
- Microsoft Azure: Power and cooling issues in West US 2, May 29, 2026
- Google Cloud: Power and cooling failure in europe-west4-a, July 15, 2026
- Blacksmith: Phoenix facility cooling loss, August 13, 2026
- Meta: The Llama 3 Herd of Models (2024), section 3.3.4
- Open Compute Project: Cold Plate Requirements and Accepted Contributions
- Vertiv: Understanding Coolant Distribution Units for Liquid Cooling